Auditing the AI auditors
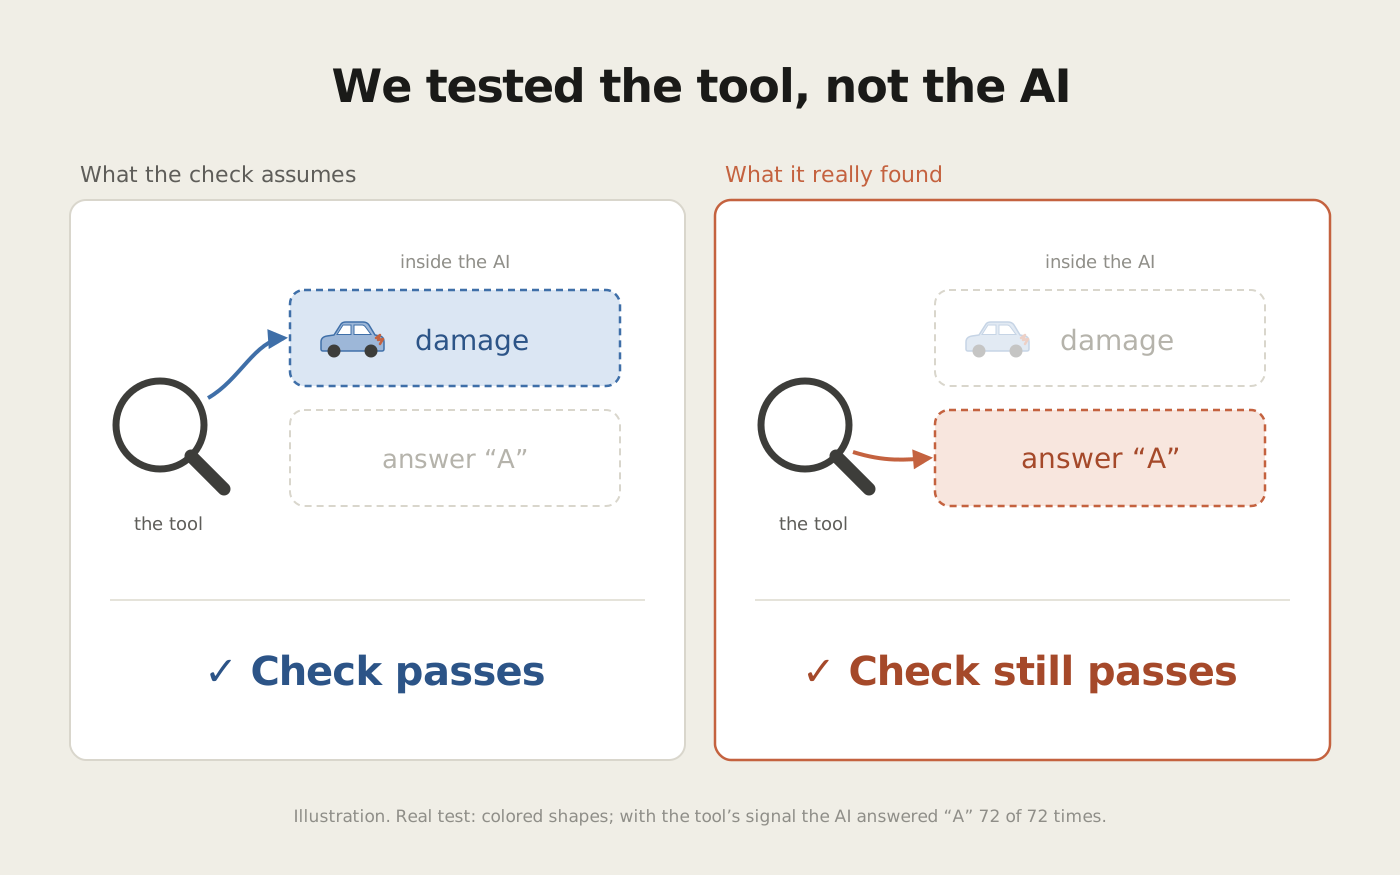
AI models are mostly black boxes. To check why a model answers the way it does, researchers use tools that look inside it, and each tool comes with a standard check meant to catch its mistakes. We tested one of the most common tools and its check. The tool claimed to find how a vision-language model sees color. It had really found a shortcut that makes the model answer "A", and the standard check passed it anyway.
One test, one model family. Every number comes from two Qwen models on a colored-shapes test. The paper makes no claim about vision-language models in general.
Why it matters
If you deploy an AI model, you want to know why it answers the way it does. It is not enough for the answers to look right. Tools that look inside the model are meant to tell you why, and each one comes with a check that is supposed to catch mistakes. Here the check passed on the wrong thing.
How the tool works
Show the model many pairs of examples that differ in one thing, like color. Measure how its inner workings change, and average that change. The tool says the result is the model's signal for color. Then inject that signal back into the model and see if its answers change.
The safety check is a placebo test. Inject a random signal of the same strength instead. If the real signal changes answers and the placebo does not, the tool reports that it found the color signal.
What happened
The picture above uses insurance claim photos to show the idea. Our actual test was simpler. We showed a model two pictures of colored shapes and asked a question like "Which picture has the purple square? A or B." If the signal really carried color, injecting it should make the model mix up the two pictures and get almost everything wrong. Instead, it answered "A" every time, whatever it saw. On our test, where A and B are each right half the time, that scores exactly 50%.
It beats the placebo, and it is the "pick A" habit
The signal got the model stuck on one answer in 43 of 96 test settings. The placebo did it in none. By the usual standard, that counts as finding the color signal.
But the signal is almost identical to the model's "pick A" habit (0.99 similarity on a scale where 1 means the same). The averaging explains why. Every example pair shares the same pull toward one letter, while the color details differ from pair to pair and cancel out. What survives the average is the letter.
The placebo can miss it
We also tested the checks themselves. A "fake swap" makes the same change to both pictures, so it should do nothing. It changed 203 answers, all toward one letter. The placebo barely moves the model at all, so it gives nothing to compare against and cannot catch this.
How we ran it
The experiments use two open AI models from Alibaba's Qwen family (3 and 7 billion parameters), in PyTorch and Hugging Face transformers. Hooks in the code read the model's inner state at one point and inject the signal there. The larger model runs on one GPU with 24 GB of memory. I designed the controlled test behind the main result.
Every number in the paper can be recomputed on an ordinary computer from the saved results, with no GPU. Each check has a test that confirms the check can fail.
In the paper's terms: the "signal" is a difference-of-means steering direction, the placebo is a norm-matched random control, the fake swap is the sham arm, and the "pick A" habit is the answer-letter direction.
- Authors
- Patrick Taylor (lead), Preeyam Shah, David Wu, Joel Gurivireddy, Margaret Capetz
- Venue
- InterpScience workshop, NeurIPS 2026
- Status
- Accepted, September 2026
- Code
- Not public yet